Audio separation for sports · Live for enterprise
Remove crowd noise from sports audio, live
Commentary on one stem. Stadium, crowd and engines on the other. In real time or after the final whistle.

Live
Your live feed, back as two streams in real time. Enterprise, on requestBatch
Recordings and archives, in Studio or by API
Live sports broadcasts powered by CAMB.AI


CAMB.AI runs live multilingual broadcasts for Major League Soccer and the Australian Open. Audio separation adds clean commentary and atmosphere to the same live workflow. See our sports work
Built for
From the stadium to the archive
Leagues and rights holders
Clean commentary for every market, and the atmosphere for partners who add their own.
Broadcasters
World feeds without commentary, and a clean voice for live translation.
Production companies
Pitch-side, tunnel and mixed-zone interviews, clean enough to publish.
Motorsport
Engine, wind and pit-lane noise out of driver and reporter voices.
Archives
Old matches and highlights re-cut with clean commentary.
The problem
The best moments are the loudest
Goals, finishes and pit stops happen when the crowd and the engines are at their peak. That is exactly when commentary, interviews and team radio get buried.
Crowd noise removal gives you the voice back without losing the moment.
Separation vs noise reduction
Separate the voice. Don't just turn the noise down.
| Noise reduction | CAMB.AI audio separation | |
|---|---|---|
| What you get | One cleaned-up track | Two stems: commentary and atmosphere |
| Crowd and engines | Turned down in the same track | Kept on their own stem, ready to remix |
| Use the atmosphere | No | Yes |
Side by side
Cleaner than AudioShake and ElevenLabs on all 8 measures
Tap a stem to hear it
Less noise between words
vs AudioShake
vs ElevenLabs
Quality
Tested on real-world audio
In our benchmark on seven real-world clips, including live TV and outdoor interviews, CAMB.AI left the least voice in the background stem: 0.376%, versus 0.437% for AudioShake and 0.447% for ElevenLabs.
The least voice left behind
14% less than AudioShake, 16% less than ElevenLabs, 29% less than LALAL.AI: a background stem you can really reuse.
Average probability that speech is still heard in the background stem.
The cleanest voice of the four
2.8× AudioShake and 1.7× ElevenLabs on how cleanly the voice is pulled from the mix.
SI-SDR, estimated by SQUIM: how much of the separated voice is the voice and not what was around it.
The least voice left behind
14% less than AudioShake, 16% less than ElevenLabs, 29% less than LALAL.AI: a background stem you can really reuse.
Average probability that speech is still heard in the background stem.
The voice that sounds best
24% above AudioShake and 23% above ElevenLabs on how good the separated voice sounds.
PESQ, estimated by SQUIM: perceived speech quality, without a reference recording.
The voice that is easiest to understand
Every word stays clear, ahead of all three.
STOI, estimated by SQUIM: how intelligible the separated speech is.
The most voice in the voice stem
23% above AudioShake and 13% above ElevenLabs.
Average CLAP speech-focus gap: how clearly the foreground stem is about speech.
| Measure | CAMB.AI | AudioShake | ElevenLabs | LALAL.AI |
|---|---|---|---|---|
| Separation quality (SI-SDR) | 2.84 dB | 1.01 dB | 1.64 dB | 2.81 dB |
| Voice left in the background (Leakage) | 0.376% | 0.437% | 0.447% | 0.529% |
| Perceptual quality (PESQ) | 1.895 | 1.527 | 1.544 | 1.852 |
| Intelligibility (STOI) | 0.744 | 0.697 | 0.726 | 0.740 |
| Voice kept in the foreground (CLAP gap) | 0.258 | 0.209 | 0.229 | 0.255 |
| DNSMOS speech quality (SIG) | 2.662 | 2.387 | 2.523 | 2.684 |
| DNSMOS background quality (BAK) | 2.884 | 2.307 | 2.538 | 2.973 |
| DNSMOS overall quality (OVRL) | 2.303 | 1.923 | 2.094 | 2.327 |
Internal benchmark: CAMB.AI, AudioShake, ElevenLabs and LALAL.AI on the same seven clips from Wikimedia Commons (gaming commentary, a film trailer, live music, an outdoor interview, a live newsroom, archival TV and a red carpet interview), averaged. SQUIM and DNSMOS are reference-free estimates. On the three DNSMOS scores LALAL.AI is slightly ahead; CAMB.AI leads every other measure.
Use cases
Commentary isolation, from stadium to race track
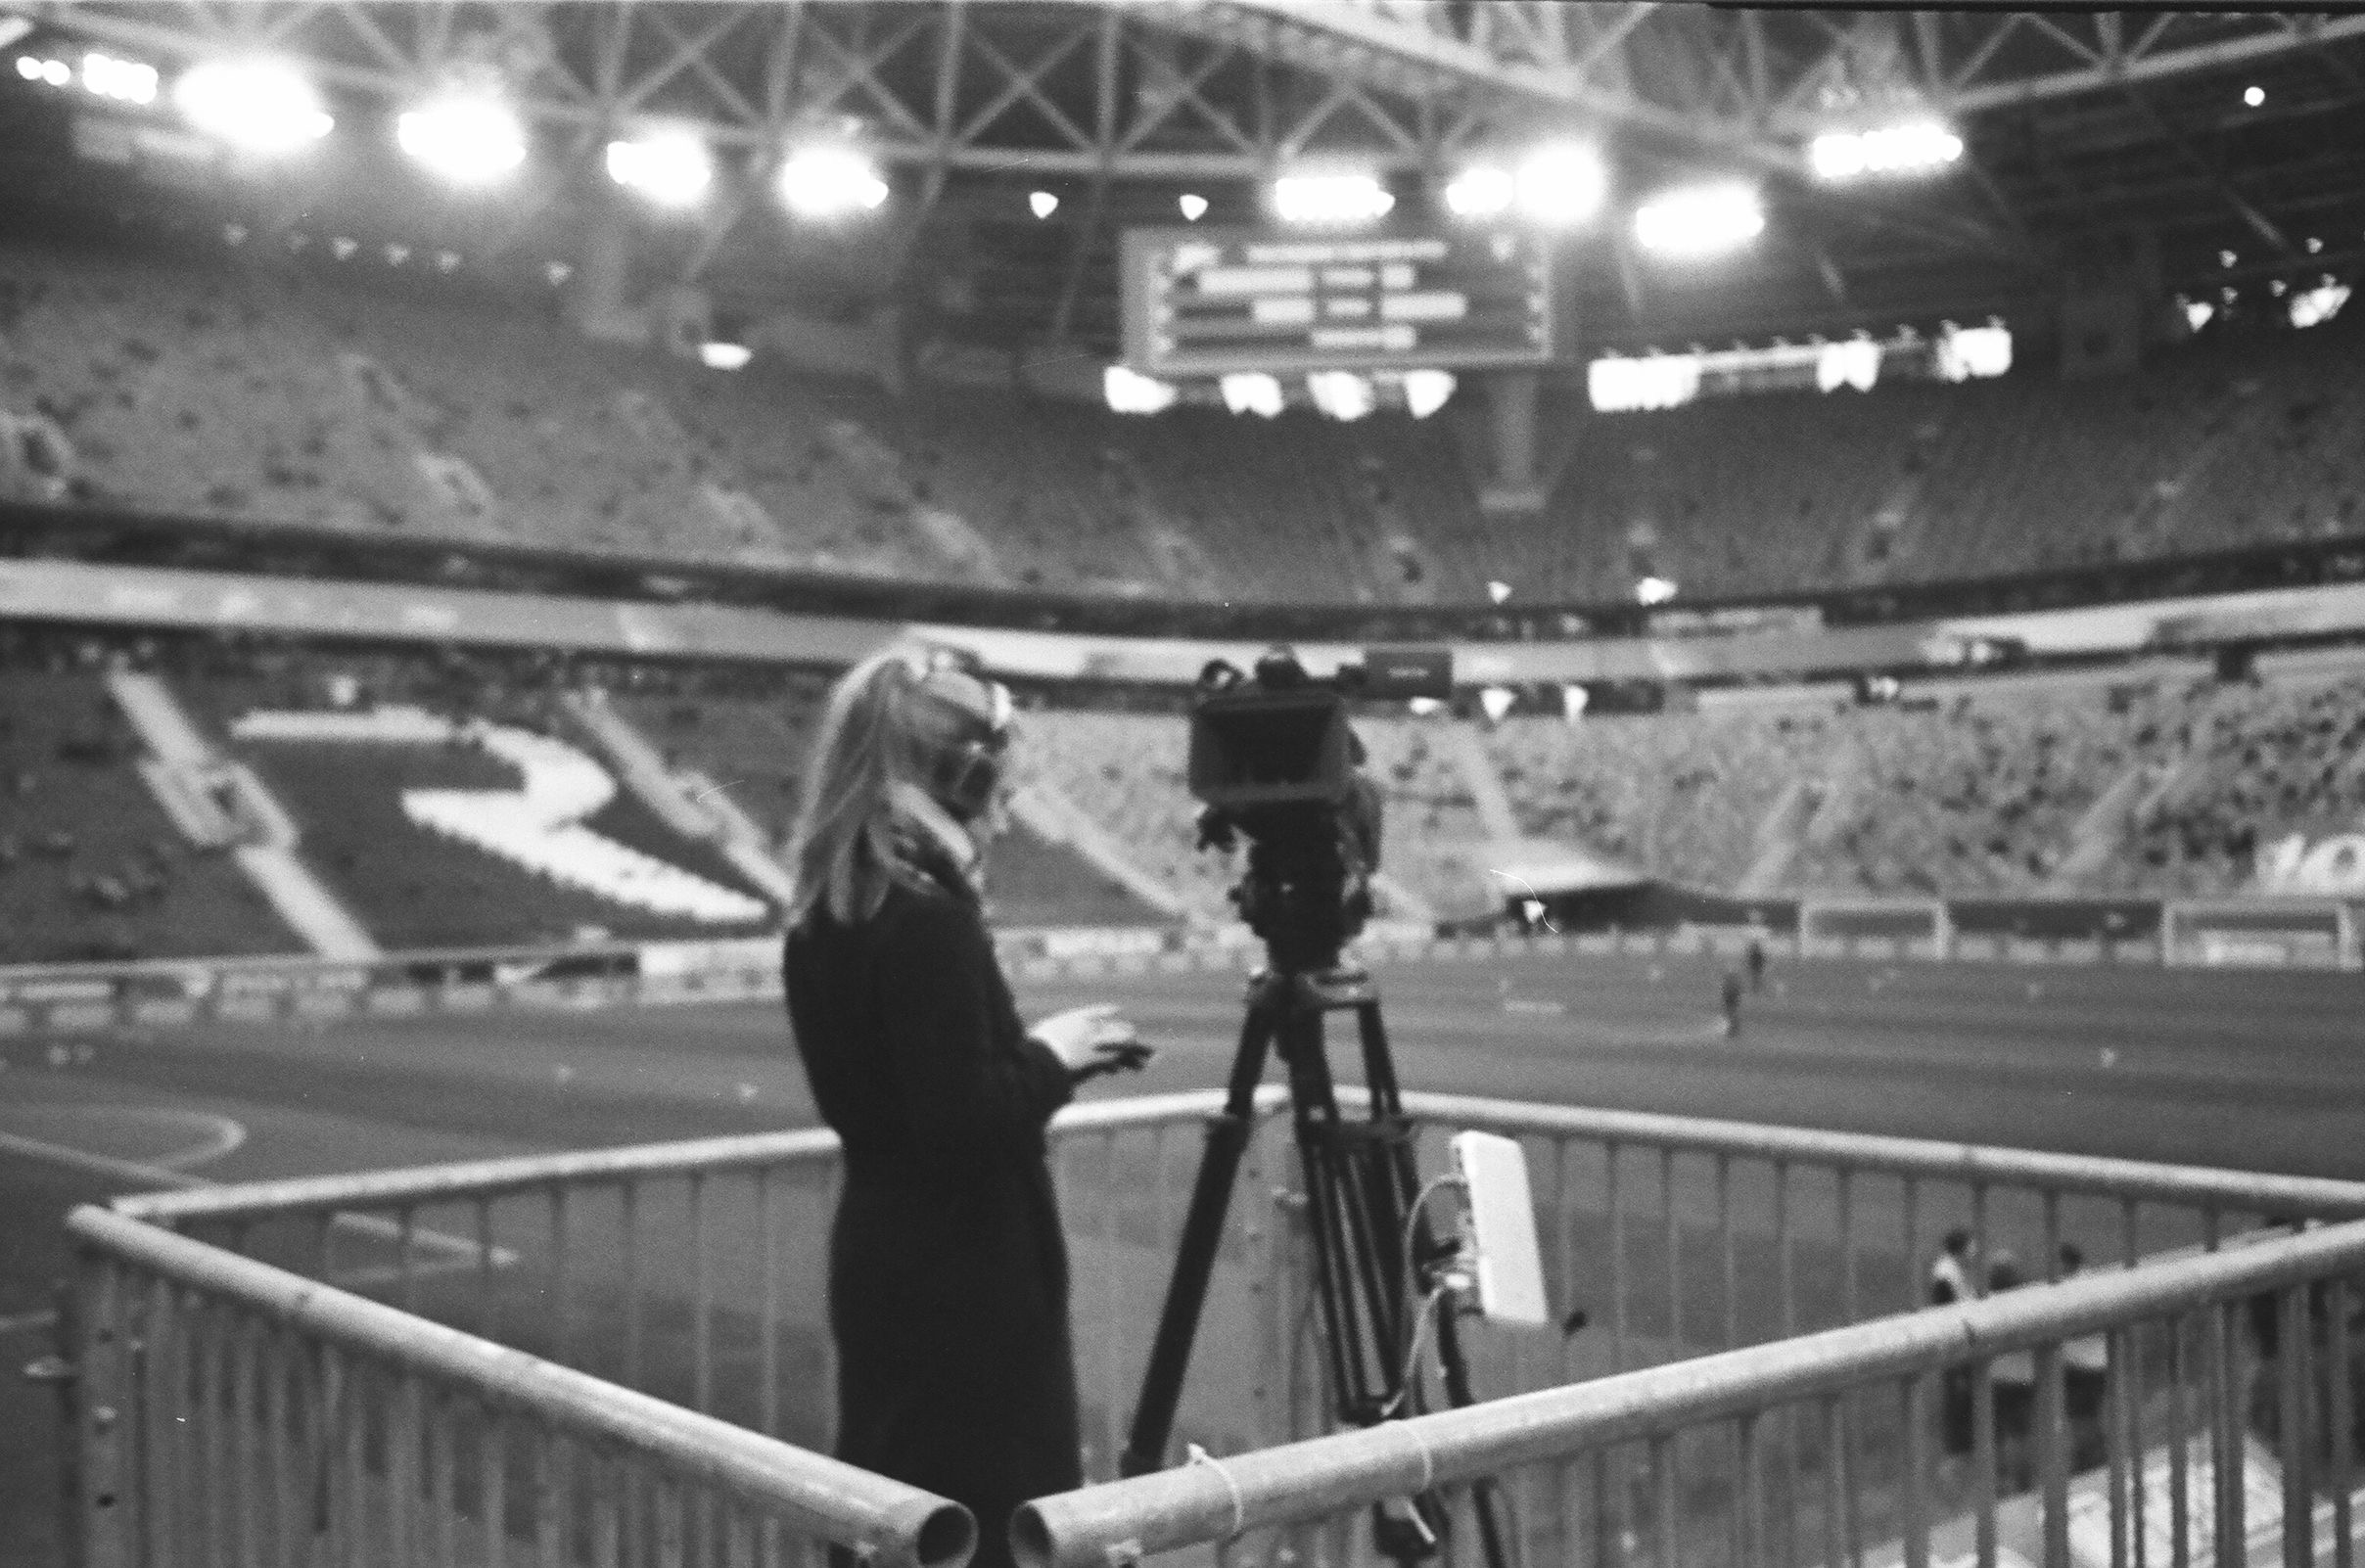
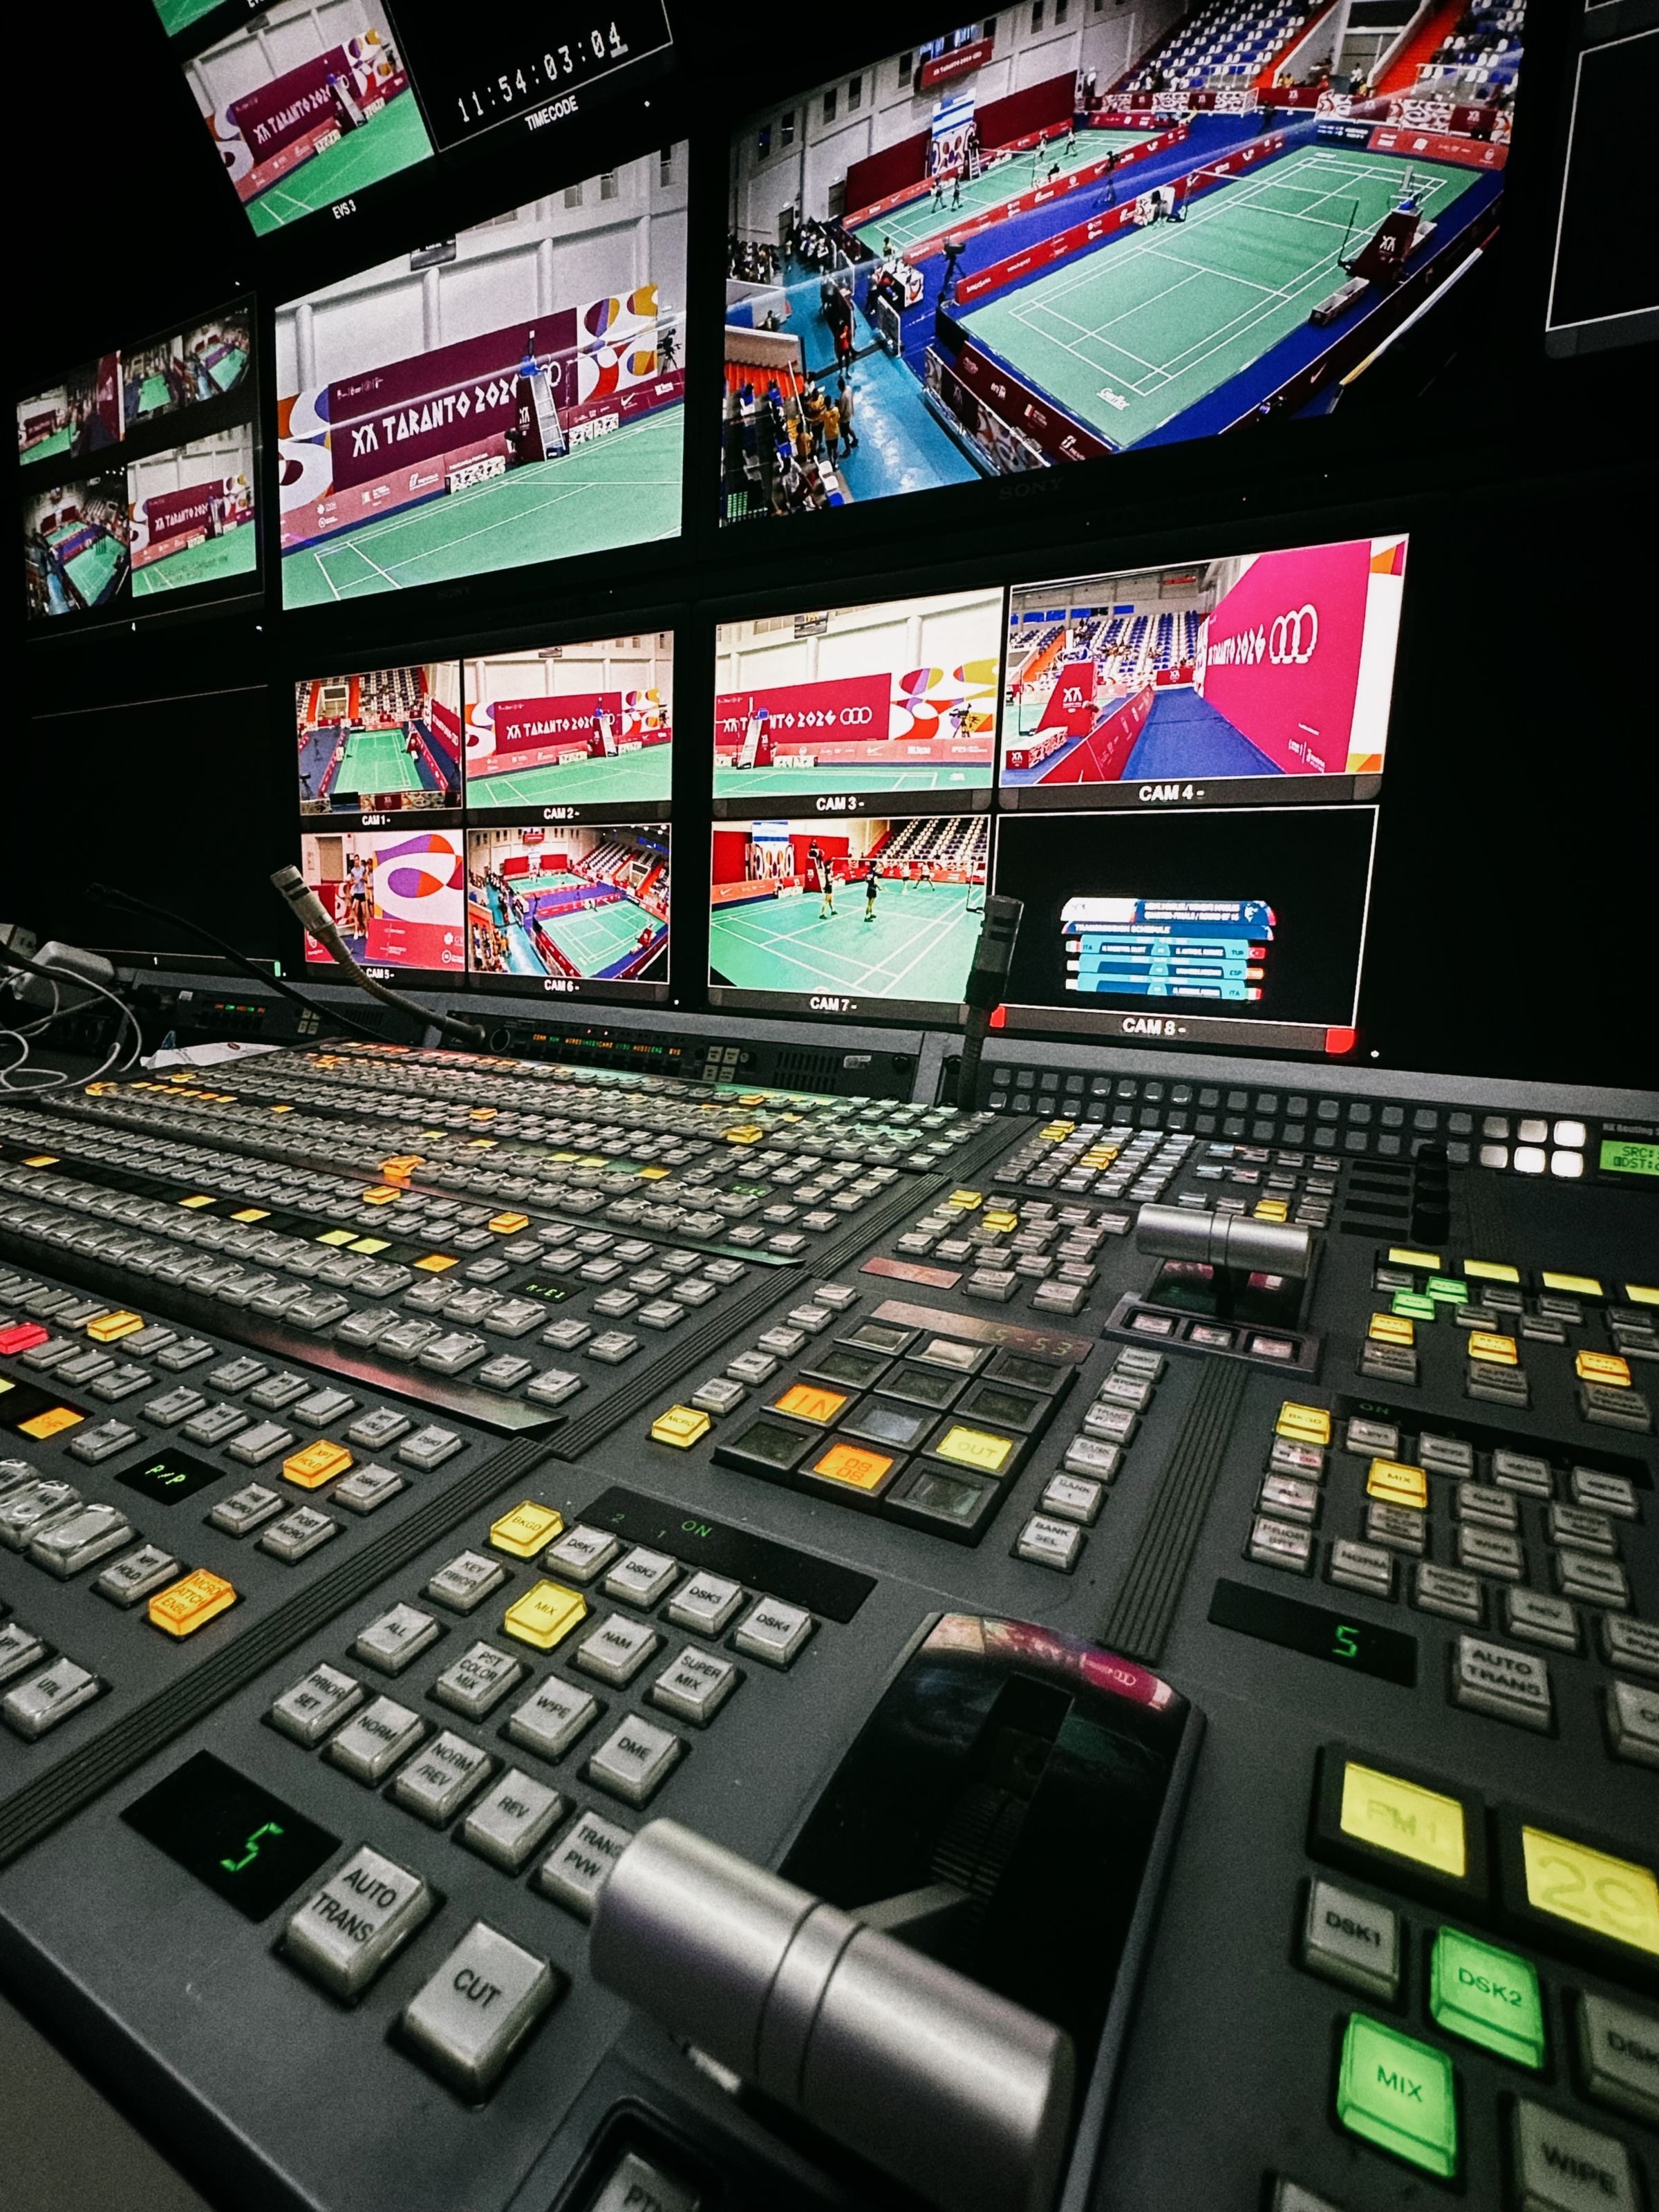
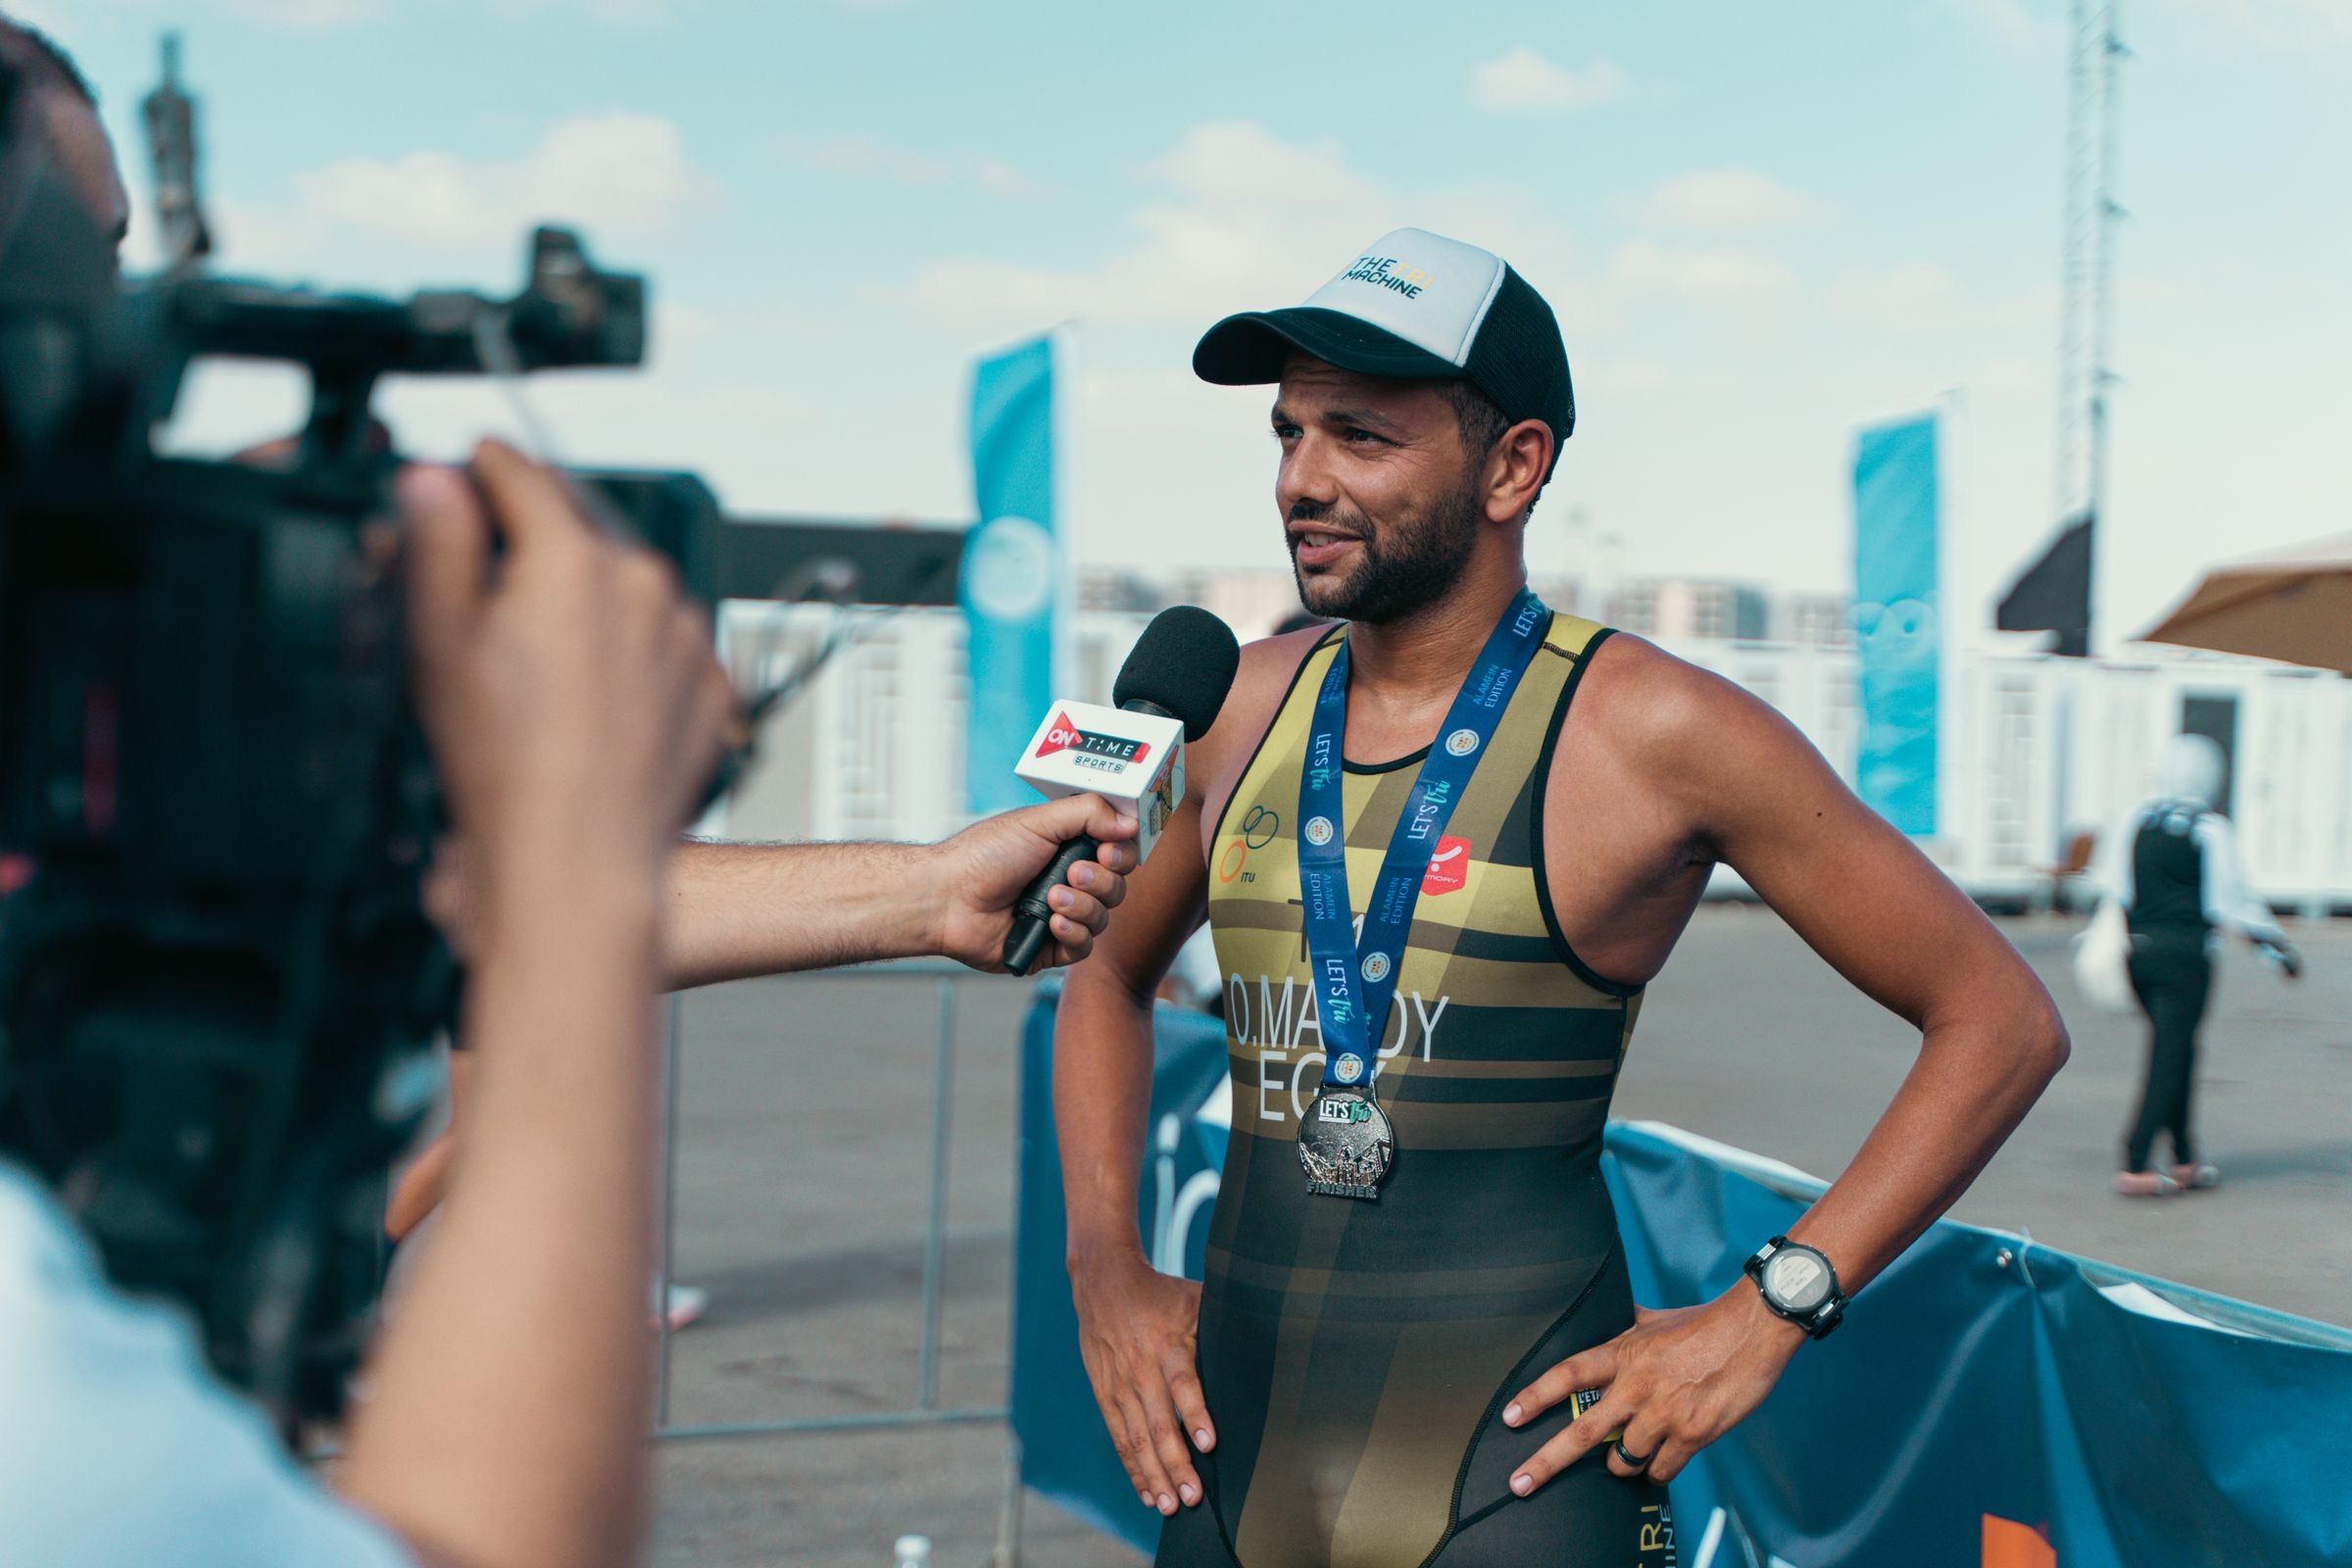
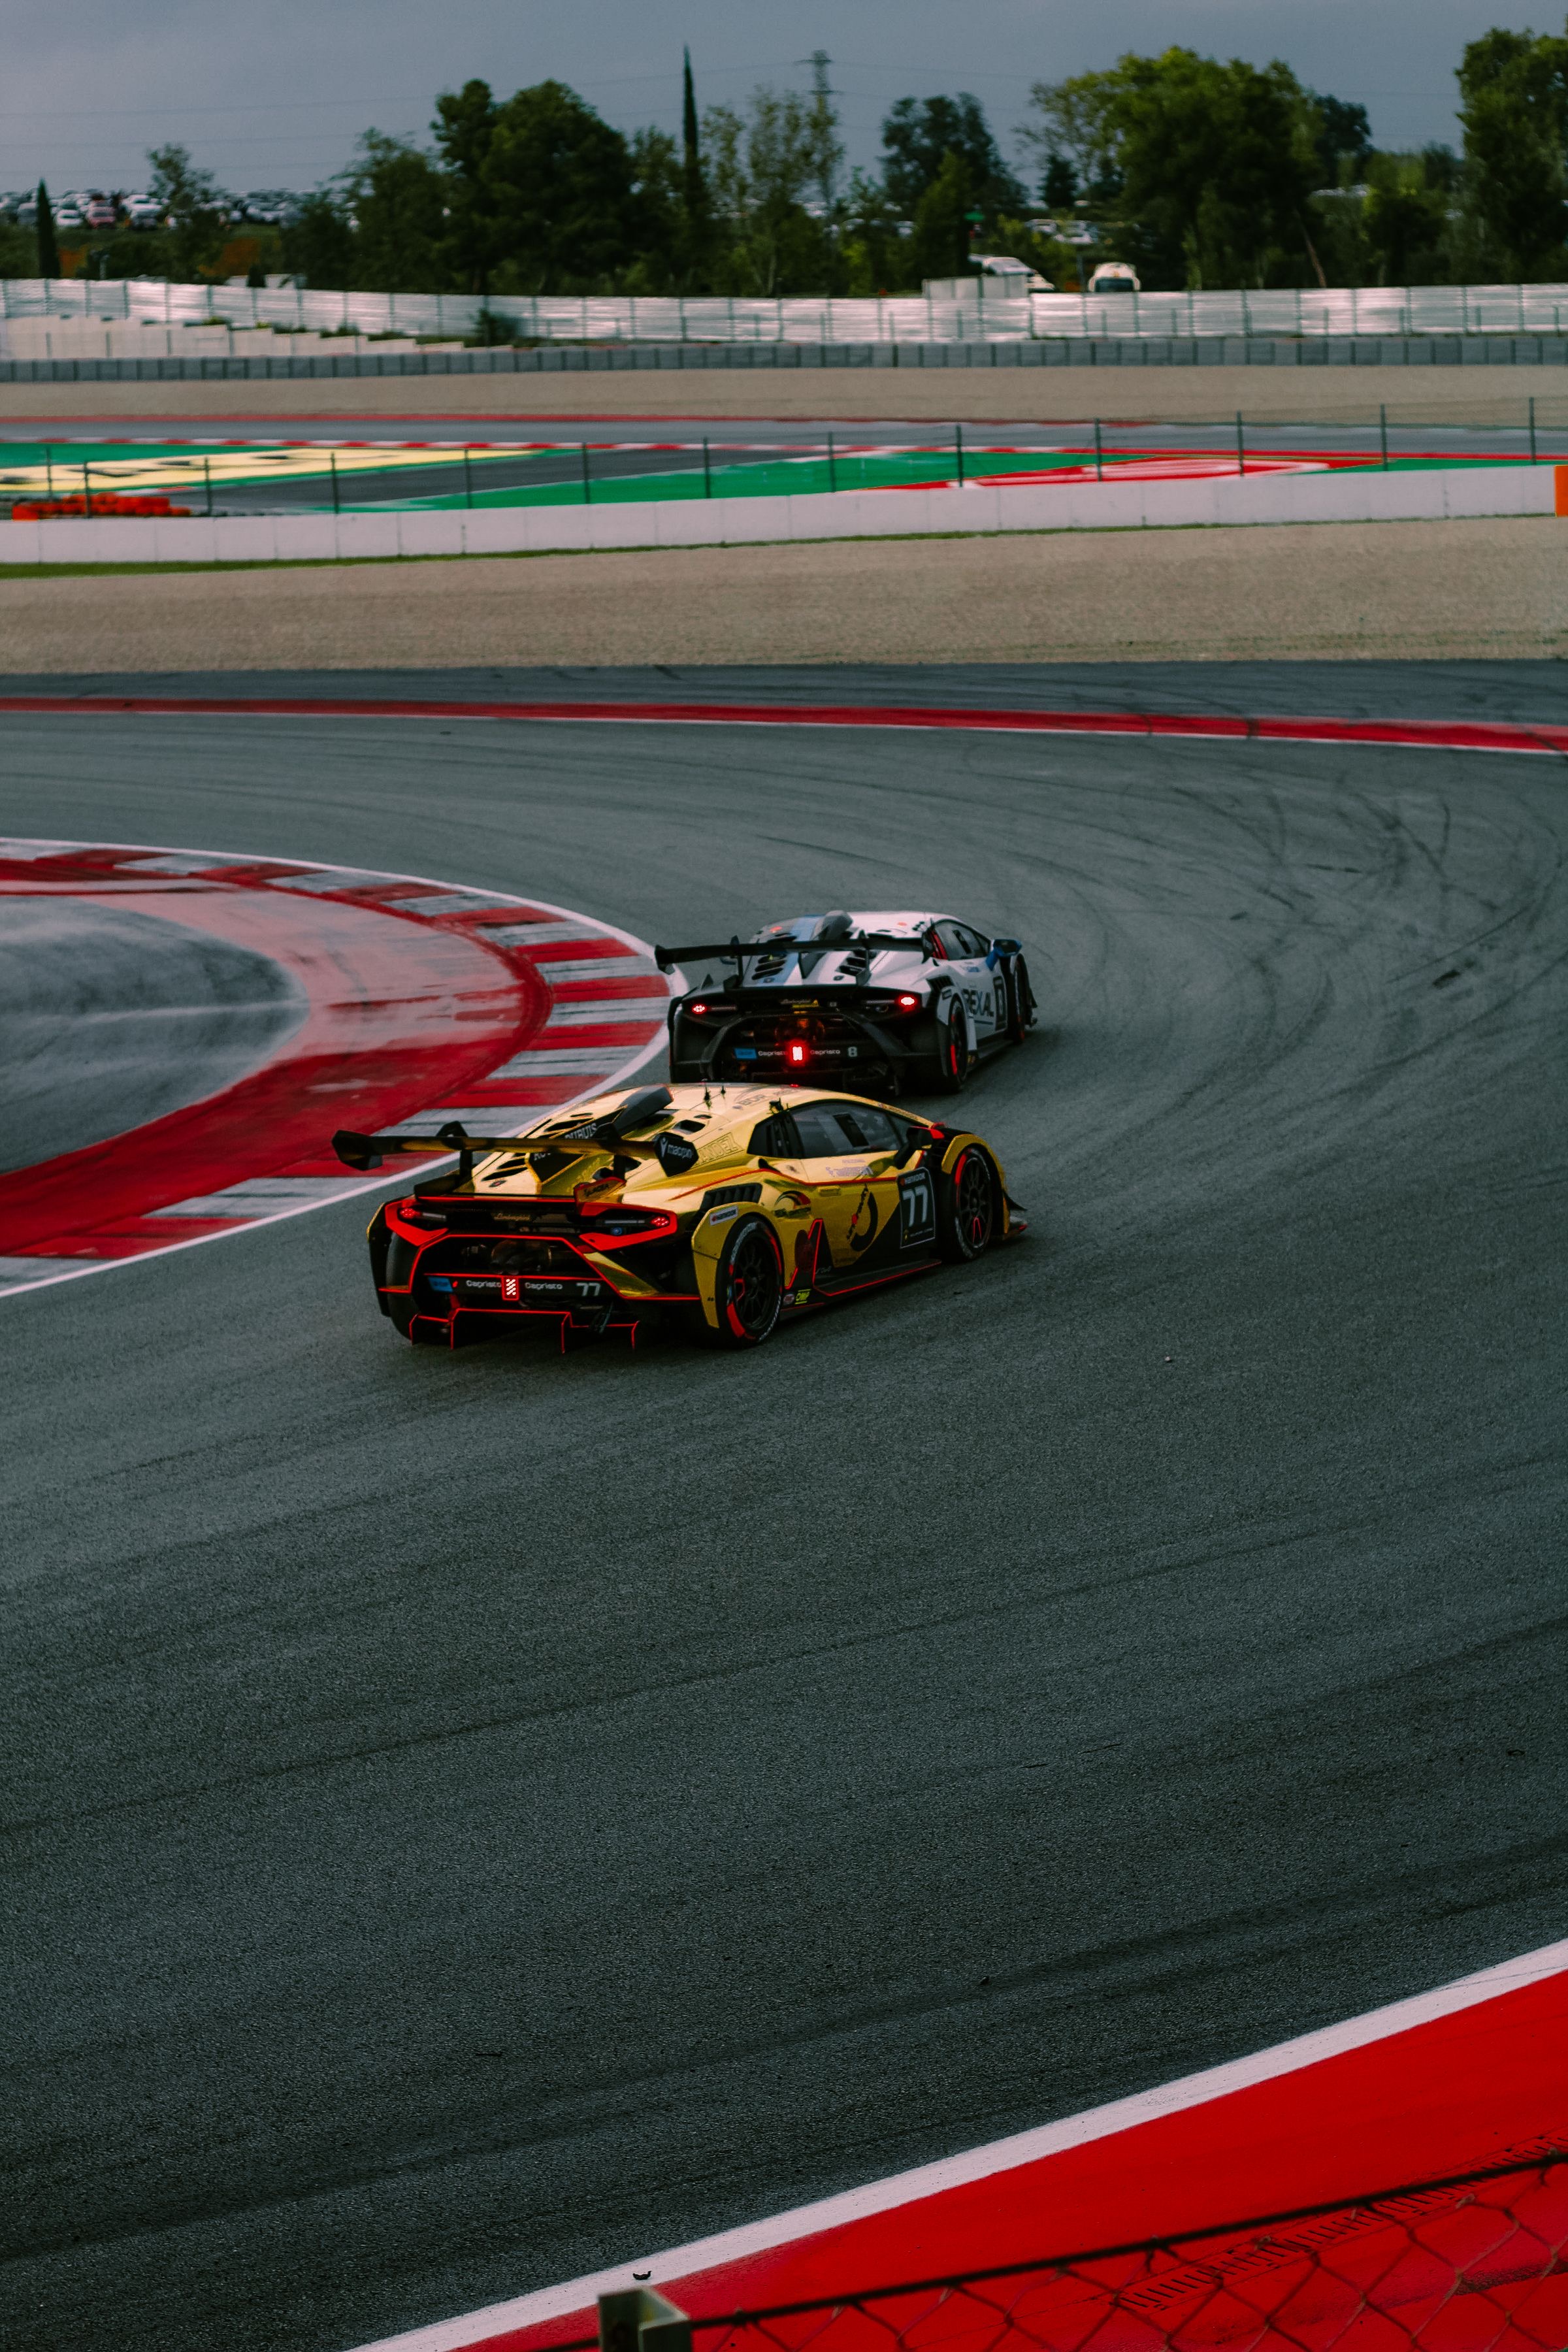
What you get
Two stems from every feed
Voice
Commentary, sideline reporters, post-match interviews, driver and team voices.
Atmosphere
Crowd, chants, engines, PA and stadium sound, without the voice on top. Everything that isn't voice stays together in the atmosphere stem, including music.
Built for live sports audioEnterprise
Your live feed, back as voice and atmosphere in two separate streams, in real time. An enterprise feature, set up with your team on request.
Talk to usAfter the match
Upload recordings and download both stems as FLAC, WAV, MP3 or AAC.
API
Automate it inside your production workflow.
POST /apis/audio-separationGET /apis/audio-separation/{task_id}GET /apis/audio-separation-result/{run_id}POST /apis/audio-separation-resultsSee the audio separation API
More audio separation
How it works
Remove crowd noise in three steps
Pricing
Pick your hours. Both stems in every plan.
Every plan gives you the voice and the background as two stems, in Studio and by API. Try any plan free for 3 days, with 30 minutes of audio.
Solo
$40/month
$480 billed yearly
3 hours of audio a month
For creators and hobbyists. Pull the voice out of songs, podcasts and videos in minutes.
Start free trial- Today 30 minutes to try. $0 today.
- Day 3 Your plan starts: $480 a year.
Session
Recommended$130/month
$1,560 billed yearly
10 hours of audio a month
For producers and content creators working every week. Enough for full albums, podcasts and soundtracks.
Start free trial- Today 30 minutes to try. $0 today.
- Day 3 Your plan starts: $1,560 a year.
Catalog
$375/month
$4,500 billed yearly
30 hours of audio a month
For professionals and teams at volume. Clean voice and background stems for music, post-production and localization.
Start free trial- Today 30 minutes to try. $0 today.
- Day 3 Your plan starts: $4,500 a year.
Enterprise
High volumes, live separation on your own feeds, or separation inside your own workflow.
- Live separation, in real time
- Volume pricing
- SLA and dedicated support
- Custom delivery and storage
FAQ
Questions about sports audio separation
Hear your own match, separated
- SOC 2 compliant
- Your audio isn't used to train our models
- Batch and live